
https://www.bbc.co.uk/news/articles/cx2z421xe0zo?at_medium=RSS&at_campaign=rss
#BBC
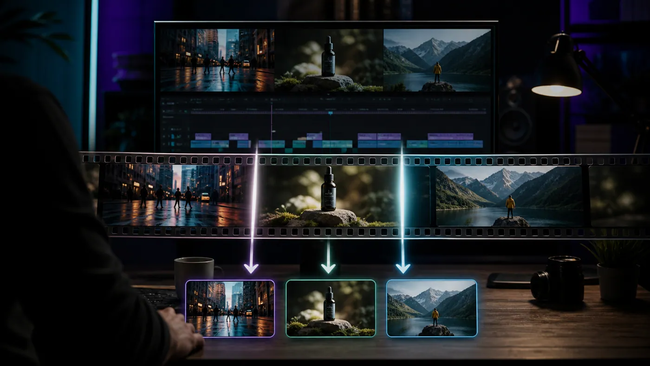
For visual creators, a flattened export can still contain a library of reusable shots. This board edition shows how to choose scene detection, fixed-duration cuts, or equal parts, then review boundaries before exporting individual MP4 clips.
Disclosure: I work with PixMind.
Key Takeaways
- Choose Scene changes when an edited video contains visible hard cuts between shots.
- Choose Fixed duration when each clip needs a repeatable length, or Equal parts when you need an exact file count.
- The current tool accepts MP4, MOV, and WebM files up to 100 MB and 120 seconds, processes them in the browser, and exports separate MP4 clips or one ZIP.
What does splitting a video by scene mean?
Scene-based video splitting finds substantial visual changes between consecutive frames and uses them as clip boundaries. A new camera angle, a hard edit, or a switch from a product close-up to a wide shot can create a boundary. Movement within one continuous shot should not.
This differs from cutting at arbitrary timestamps. A source with three visible shots can produce three independent clips. A continuous take with no clear edit may remain one clip.
Scene splitting is useful when the original editing project is unavailable. It will not rebuild the source timeline, effects, or layers, but it can recover practical shot-level files from an ad reference, montage, storyboard export, or approved social video.
Choose the split mode that matches the next task
The right mode depends on what must remain predictable: the visual boundary, the duration, or the number of files.
Mode How cuts are chosen Best for Output behavior
| Scene changes | Detects substantial visual transitions | Edited ads, reels, montages, and storyboard exports | One MP4 for each detected section
| Fixed duration | Cuts after a chosen number of seconds | Social segments, review batches, and delivery limits | Repeated lengths, with a shorter final clip when needed
| Equal parts | Divides total duration by a chosen clip count | Predictable handoffs and parallel review | Exactly 2 to 20 balanced clips
Use one decision rule: let content choose the boundary for edited footage, let time choose it for repeatable publishing slots, and let file count choose it for a fixed handoff. Scene detection is not automatically the best mode for every video.
How browser-based scene splitting works
The workflow has two distinct stages: finding boundaries and creating files.
The detector compares decoded video frames
The scene mode reads the primary video track from the selected file, decodes its frames, reduces them for analysis, and compares hue, saturation, and brightness features between neighboring frames. It uses an adaptive baseline, filters brief flashes, and groups candidates that are too close together.
That design explains both strengths and limits. Hard cuts create a strong difference and are easier to find. Slow dissolves, two similarly composed shots, exposure changes, or very fast motion can create weaker or misleading signals.
The implementation uses browser media interfaces exposed through Mediabunny. Its official Reading media files guide documents reading a user-selected File, checking whether a track can be decoded, and accessing frame-timed media data. The underlying W3C WebCodecs specification defines JavaScript interfaces for browser audio and video codecs.
Each result is rendered as a new MP4
After boundaries are ready, the splitter uses ffmpeg.wasm to create each segment. The ffmpeg.wasm overview describes the project as a WebAssembly and JavaScript port of FFmpeg that runs media processing inside browsers.
The current export path re-encodes video as H.264 and audio, when present, as AAC. The official FFmpeg Codecs Documentation documents the libx264 wrapper and native AAC encoder used by that command. This produces consistent MP4 files and avoids empty or repeated segments around seek points, but it is not a lossless stream copy. Rendering therefore takes longer than calculating timestamps alone, especially for higher-resolution or higher-frame-rate inputs.
How to split a video into scene clips
1. Add a compatible short video
Choose an MP4, MOV, or WebM file no larger than 100 MB and no longer than 120 seconds. The file must meet both limits.
Edited sources with deliberate cuts work best. Good candidates include product montages, short commercials, social reels, animatics, and reference clips you want to inspect shot by shot. If the browser cannot decode the source codec, export a standard MP4 and try again.
2. Select Scene changes
Choose Scene changes under “How should this video be split?” This tells the tool to inspect the visual content rather than apply a fixed schedule.
If the source is one continuous take, skip detection and choose Fixed duration or Equal parts instead.
3. Detect scenes and create the clips
Select Detect scenes and split. Progress covers both analysis and MP4 creation. The selected source stays on the device rather than being uploaded to product storage.
The first run may start more slowly while the browser prepares its media-processing components. Duration, resolution, frame rate, and output count all affect local processing time.
4. Preview every boundary
Each result shows a clip number, start time, end time, and duration. Check the clips immediately before and after every proposed cut:
- Does the previous shot end cleanly?
- Does the next clip begin on the intended image?
- Was a flash or exposure change mistaken for an edit?
- Did a dissolve remain inside one clip?
This review is still necessary because scene detection evaluates visual change, not story meaning or dialogue.
5. Download one MP4 or the complete ZIP
Download individual clips when only a few shots are useful. Choose Download all as ZIP when the complete batch will move into an editor, review queue, or asset library.
When each split mode works best
Scene changes for edited footage
Use visual transitions when the source already contains meaningful edits. Choose time or file count only when delivery constraints matter more than shot boundaries, and always review the clips on both sides of every detected cut.
Originally published by the PixMind Editorial Team
https://www.pixmind.io/posts/split-video-into-clips-by-scene
For visual creators, a flattened export can still contain a library of reusable shots. This board edition shows how to choose scene detection, fixed-duration cuts, or equal parts, then review boundari...
Choosing a video prompt extractor is less about finding the tool with the longest feature list and more about matching the output to the next production step. A creator who needs a reusable storyboard has different requirements from a developer who needs JSON or a marketer working from a public YouTube link.
Disclosure: I work with PixMind. This Ziney edition keeps the comparison transparent: it does not assign invented accuracy scores, and it separates verified workflows from practical trade-offs.
Quick comparison
Tool Best for Accepted input verified from the live product Most useful output Main trade-off
| PixMind Video to Prompt | Shot-by-shot creative production | Video upload and direct video URL | Master prompt, timestamped shot breakdown, camera/action/light/audio fields, batch mode, Excel export | Public YouTube page URLs are not currently accepted
| Short.ai Video to Prompt | URL-to-script workflow | Public YouTube and TikTok links under five minutes | Editable scene script with characters, camera, setting, mood, and audio | Optimized around supported public platform links
| Vora Video to Prompt | Quick multilingual prompt extraction | File upload or video link | Editable prompt text with optional context and language selection | The public workflow emphasizes a consolidated prompt more than a production shot table
| Video2Prompt | JSON export and automation | File, TikTok, YouTube, Vimeo, and direct media links | Shot JSON, text prompt, timing, first-frame and audio fields | Its own page recommends clips of about two minutes or less for the most reliable breakdown
| Gemini API video understanding | Custom developer pipelines | File API, Cloud Storage, inline video, and public YouTube URLs | Any schema you design, including timestamps and audio/visual details | Requires API work; default 1 FPS visual sampling can miss fast cuts
What is a video prompt extractor?
A video prompt extractor analyzes an existing clip and turns it into a reusable text description. It does not recover the original secret prompt with certainty. Many videos were edited from multiple generations, camera footage, voice tracks, music, captions, and transitions. The practical goal is to reconstruct a useful creative specification.
A production-ready extraction normally has two levels:
- Master prompt: the overall subject, setting, visual style, mood, color, motion language, and audio direction.
- Shot prompts: a timeline that explains what changes from one cut to the next.
That distinction matters. A one-paragraph summary may be enough for visual inspiration, but it cannot reliably recreate a 20-shot montage or become a shooting script.
How we compared the tools
This is a workflow comparison, not a fabricated laboratory ranking. We checked five questions:
- Can the tool accept a local file, a direct video URL, or a public platform URL?
- Does it separate shots and preserve time or duration?
- Does it distinguish subject action from camera movement?
- Does it include lighting, dialogue, sound effects, on-screen text, and transitions?
- Can the output be edited, copied, downloaded, exported, or passed into another production step?
We used four real examples already available in PixMind’s feature page as the evaluation set:
Existing PixMind case Duration Published breakdown What it tests
| Cinematic secret-garden montage | 19.9 seconds | 20 shots | One-second cuts, close-up/wide-shot alternation, subject continuity, music
| Product showcase | 16.4 seconds | 7 shots | Product actions, visible text, clean before/after sequence, sound cues
| 3D social narrative | 88.2 seconds | 12 scenes | Characters, dialogue, story progression, longer scene timing
| Cinematic food close-ups | 27.3 seconds | 23 shots | Rapid macro edits, ingredients, camera scale, cooking sounds
These cases are useful because they expose different failure modes. A tool can look impressive on one slow landscape shot and still collapse when it sees rapid cooking cuts, overlaid text, or a dialogue-heavy sequence.
1. PixMind Video to Prompt — best overall for structured production
PixMind Video to Prompt is designed around a storyboard rather than a single paragraph. It accepts an uploaded video or a direct media URL, then returns an overall prompt and a shot list. Each shot can include:
- time and duration;
- scene and framing;
- visible action;
- camera position or movement;
- color and lighting;
- dialogue and on-screen text;
- sound effects;
- transition;
- a copy-ready shot prompt.
The result can be reviewed in the browser, copied shot by shot, reformatted for supported platforms, or exported to Excel. Batch mode is useful when a creator needs to process a folder of references instead of one clip.
The product-showcase example demonstrates why field-level output is more useful than a generic summary:
Shot 1 — 00:00–00:01.5: Close-up of a hand holding a white electric spin scrubber, followed by cleaner sprayed onto a black glass stovetop. Static close-up; bright modern kitchen; spray sound and upbeat music; on-screen product text; cut transition.
That row gives an editor or prompt writer concrete variables to change. You can preserve the camera and action, replace the product, remove the on-screen copy, or change the lighting without rewriting the full sequence.
Choose PixMind when: you need a reusable storyboard, multiple output languages, batch processing, or an Excel handoff to a creative team.
Current limitation: the URL field accepts direct video media, but not a standard YouTube watch-page URL. For YouTube workflows, use a supported source file or follow the YouTube video-to-prompt workflow.
2. Short.ai Video to Prompt — best for public YouTube and TikTok scripts
Short.ai’s Video to Prompt tool focuses on a link-first workflow. Its live page says it currently accepts public YouTube and TikTok videos under five minutes. The output is positioned as an editable, shot-by-shot script that covers characters, settings, camera angles, mood, and audio elements.
Its differentiator is what happens after extraction: users can edit scene elements and continue into Short.ai’s video-generation workflow. That makes it attractive when the desired deliverable is a revised script and regenerated video rather than a neutral export.
Choose Short.ai when: the source already lives on YouTube or TikTok and you want to modify the extracted scenes inside one creation flow.
Trade-off: its public page describes a workflow centered on supported platform links. If you primarily analyze local client footage, direct media files, or batches, verify that the current input route fits your project before committing.
3. Vora Video to Prompt — best for a fast multilingual prompt
Vora by FineShare exposes both Add Link and Upload File inputs, an optional context field, and a prompt-language selector. Its published output coverage includes scenes, style, actions, dialogue, camera movement, background sound, transitions, and color grading. The resulting prompt can be copied or downloaded.
This is a practical fit for someone who wants a fast consolidated description and does not need a large storyboard table. The optional context field is useful: you can tell the analyzer to prioritize wardrobe, transitions, product placement, or camera language before it processes the clip.
Choose Vora when: speed, link/file flexibility, and multilingual prompt text matter more than a deeply structured handoff.
Trade-off: the public page emphasizes comprehensive prompt text. Teams that require strict timecodes, a repeatable per-shot schema, or automation-ready JSON should inspect the generated format before standardizing on it.
4. Video2Prompt — best for JSON and automation
Video2Prompt makes its structured output explicit. Its live product page describes both a copy-ready text prompt and shot JSON, including timing, first-frame descriptions, camera movement, lighting, audio, and transitions. It supports file upload and links from TikTok, YouTube, Vimeo, and direct media URLs.
The JSON path is the reason to shortlist it. A post-production team can validate fields, send shots into a database, generate review sheets, or connect each shot to a later generation step. Its model presets are also useful when a team wants a consistent formatting convention.
Choose Video2Prompt when: the output will feed an automation, asset-management system, or scripted production pipeline.
Trade-off: the product recommends videos of roughly two minutes or less for the most reliable shot quality, and some advanced prompt-pack behavior uses credits. Check the current plan before designing a high-volume workflow.
5. Gemini API — best for developers who need a custom extractor
Google’s official Gemini API video-understanding guide documents file upload, Cloud Storage, inline video, and public YouTube input. Gemini can describe and segment video, process audio and visual information, answer questions, and refer to specific timestamps.
The advantage is control. A developer can request a strict JSON schema such as:
{
  "shots": [
    {
      "start": "00:00.0",
      "end": "00:01.5",
      "subject_action": "",
      "camera": "",
      "lighting": "",
      "dialogue": "",
      "sound": "",
      "transition": "",
      "generation_prompt": ""
    }
  ]
}
The important technical limitation is documented by Google: visual descriptions use a default sampling rate of 1 frame per second, which may miss details in rapid motion or quick scene changes. That is exactly why our 23-shot food example is a better stress test than a slow landscape clip. A custom pipeline may need preprocessing, denser frame extraction, cut detection, or a second pass around likely transitions.
Choose Gemini API when: you need full schema control, long-video handling, repeated processing, or integration into an internal application.
Trade-off: it is a component, not a finished creative tool. You must design prompts, validation, retries, storage, review UI, and exports yourself.
The most important output fields
When comparing any video prompt extractor, inspect the result rather than the marketing headline.
1. Shot boundaries
The tool should detect actual edits and meaningful scene changes. One-second montage cuts and slow continuous shots should not be treated the same way.
2. Subject action versus camera motion
“A runner moves left” and “the camera tracks left” are different instructions. Combining them into “dynamic movement” removes the information a video model needs.
3. Time and duration
A prompt becomes easier to produce when every row includes a start, end, or duration. Timing also reveals pace: seven shots over 16 seconds feels different from seven shots over 90 seconds.
4. Lighting and color
“Warm” alone is weak. Better descriptions specify source and quality: soft window light, golden backlight, overcast diffusion, hard product lighting, or high-contrast practical light.
5. Dialogue, sound, and on-screen text
Audio often carries the structure of a short video. A useful extraction distinguishes spoken dialogue, music, ambience, sound effects, and visible captions.
6. Transitions and continuity
Cuts, fades, match cuts, speed ramps, and camera-led transitions affect how prompts should be grouped. The extractor should also preserve stable character, wardrobe, product, and environment attributes across shots.
A repeatable way to test any video prompt extractor
Do not choose a tool after analyzing one easy clip. Use three short videos:
- A slow product shot: tests object identity, material, lighting, and controlled camera motion.
- A fast vertical montage: tests cut detection, text, transitions, and one-second actions.
- A dialogue scene: tests speakers, spoken words, reaction shots, ambience, and narrative order.
For each result, count:
- missed or invented shots;
- camera movement confused with subject motion;
- missing dialogue or text;
- generic lighting descriptions;
- prompts that cannot stand alone;
- fields that are difficult to edit or export.
This produces a useful decision, even without pretending that one subjective “accuracy percentage” applies to every kind of video.
Which video prompt extractor should you choose?
- Choose PixMind for a visual, shot-by-shot workflow with editable fields, multilingual output, batch analysis, and spreadsheet handoff.
- Choose Short.ai for public YouTube/TikTok links and an integrated script-edit-to-generation workflow.
- Choose Vora for fast file-or-link input and a downloadable multilingual prompt.
- Choose Video2Prompt when JSON and automation are primary requirements.
- Choose Gemini API when your team can build and maintain a custom analyzer.
If your real goal is to turn a reference into a new AI video, extraction is only step one. Review the shot list, remove accidental brand or identity details, decide what must stay consistent, and then adapt the prompt to the target model. A Seedance prompt may emphasize reference relationships and sequence continuity; a Veo prompt can make dialogue, sound, and cinematic intent explicit; a Kling prompt often benefits from direct subject and camera-motion instructions.
Start with the free PixMind Video to Prompt tool, inspect the four published examples, and compare the result against the six output fields above. For a production-oriented breakdown, continue with How to Reverse-Engineer Video Prompts. If the deliverable is a shooting document rather than a generation prompt, use Video to Script or the AI Video Analyzer.
Frequently asked questions
Can AI recover the exact original prompt from a video?
Usually not. A finished video may combine multiple prompts, reference images, recorded footage, edits, sound design, captions, and manual color work. An extractor reconstructs a plausible and reusable specification; it does not prove which private prompt was originally used.
What is the difference between video to prompt and video to text?
Video to text may mean a summary, transcript, caption, or description. Video to prompt focuses on creative and technical instructions that can guide recreation: subject, action, camera, lighting, timing, sound, and transitions.
Is a transcript enough to recreate a video?
No. A transcript captures spoken words but not framing, visual action, camera motion, lighting, pacing, or edits. Dialogue-heavy projects often need both a transcript and a shot breakdown.
What is the best format for extracted video prompts?
Use a master prompt plus a table or JSON array of shots. Each shot should contain timing, subject action, camera, environment, lighting, dialogue/audio, transition, and a standalone generation prompt.
Can I extract a prompt from a YouTube video?
Yes, if the selected tool supports YouTube URLs and the video is publicly accessible. Short.ai, Video2Prompt, and the Gemini API currently describe public YouTube input. PixMind currently accepts uploads and direct video URLs rather than standard YouTube watch pages.
Which extractor is best for fast-edited TikTok or Reels videos?
Choose one that exposes shot boundaries and timecodes. Test it with one-second cuts before relying on it. Fast edits can be missed by systems that sample video sparsely.
Can I use the extracted prompt in Seedance, Veo, or Kling?
Yes, but adapt it rather than pasting blindly. Keep the scene facts and continuity, then rewrite the model-facing prompt around the target model’s controls, duration, reference inputs, and audio behavior.
Should I use one long prompt or separate shot prompts?
Use one long prompt only for a simple continuous shot. For a montage, ad, recipe, trailer, or narrative, separate shot prompts are easier to review, generate, reorder, and repair.
Sources checked
- PixMind Video to Prompt product and published cases
- Short.ai Video to Prompt product page
- Vora Video to Prompt product page
- Video2Prompt product page
- Google Gemini API video-understanding documentation
Originally published by the PixMind Editorial Team: 5 Best Video Prompt Extractors in 2026.
Choosing a video prompt extractor is less about finding the tool with the longest feature list and more about matching the output to the next production step. A creator who needs a reusable storyboard...
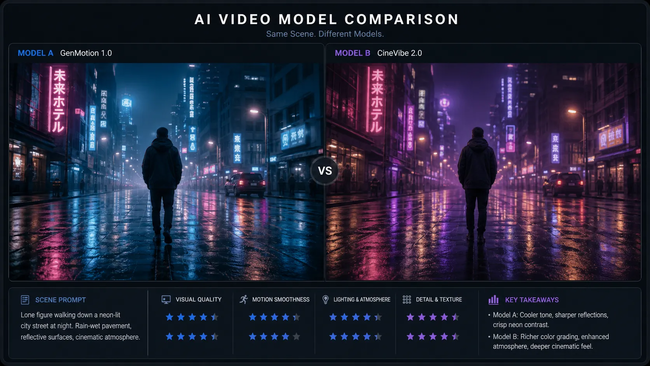
For visual creators, a model comparison should route real shots instead of declaring one universal winner. Start with the constraint that cannot fail—cinematic ceiling, native audio, character motion, reference control, turnaround, or cost per approved second.
Disclosure: I work with PixMind.
Key Takeaways
- Best value: MiniMax H3 at $0.13/sec (2K) delivers the highest quality per dollar, roughly one-third of Veo 3.1's published rate and about 23% below Kling 3.0.
- Best absolute quality: Veo 3.1 leads on 4K cinematic finish and synchronized audio, but caps clips near 8 seconds.
- Best for motion reuse: Kling 3.0's motion-transfer feature (1080p, $0.168/sec with audio) is unmatched for retargeting a known move onto new characters.
- Open-weight option: H3 is the only one of the three you can self-host, which matters for developers with privacy, latency, or cost-at-scale constraints.
- Audio is no longer a tiebreaker: all three ship native audio (H3 stereo, Kling and Veo synchronized), so the decision now hinges on resolution, length, price, and control.
Quick verdict by job
Lead with the job you need done, then pick the model. Each of these three wins a specific production scenario.
- Batch short-form content (TikTok, Reels, Shorts) on a budget: MiniMax H3. The 2K output is more than enough for vertical social, the 5 to 15-second range covers most hooks, and the per-second price keeps iteration cheap.
- Premium hero shots and brand film: Veo 3.1. When one shot has to look like a finished TV spot at 4K, Veo 3.1's cinematic quality and sync audio justify the premium.
- Reusing a real performance or camera move: Kling 3.0. Its motion-transfer feature takes a reference video's motion and applies it to a new subject, which neither H3 nor Veo does as directly.
- Self-hosted or privacy-sensitive pipelines: MiniMax H3. The open weights mean you can run it on your own infrastructure instead of sending prompts through a third-party API.
The three models at a glance
The table below collects the verified specifications for all three models, checked against MiniMax's official release notes, Kuaishou's Kling 3.0 documentation, and Google's Veo 3.1 product page as of August 2026.
Specification MiniMax H3 Kling 3.0 Veo 3.1
| Max resolution | 2K | 1080p | 4K
| Clip length | 5 to 15 seconds | 3 to 15 seconds | ~8 seconds
| Native audio | Yes, stereo | Yes, included in price | Yes, synchronized
| Reference inputs | Up to 12 | Motion-transfer reference | Standard text/image
| Standout capability | Multi-reference consistency, open weights | Motion transfer | Cinematic 4K finish
| Pricing model | $0.13/sec at 2K | $0.168/sec (audio included) | Premium per-second rate, higher than H3 and Kling
| Access | Open weight + hosted API | Hosted API | Hosted API (Google)
| Best for | High-volume, cost-sensitive production | Retargeting real motion | Hero shots and brand film
MiniMax H3 in Action: Real Comparison Examples
Before the deep dive, watch the models run head to head. The video below is a side-by-side MiniMax H3 versus Veo comparison that renders the same prompt through each model, so you can see where each one actually wins on screen.
https://www.youtube.com/embed/fU5uFVIzp_c" width="560" height="315" title="MiniMax H3 vs Veo 3 AI video comparison" frameborder="0" allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture" allowfullscreen> A side-by-side comparison renders the same prompt through MiniMax H3 and Veo to show where each model wins on detail, motion, and cinematic finish.
MiniMax's own positioning places H3 ahead of Veo and Kling on the price-to-quality curve, which is the claim the comparison video above puts to the test.
https://x.com/RyanLeeMiniMax/status/2082999154029306266">MiniMax H3 rankings vs Veo and Kling
MiniMax H3: open-weight 2K with twelve references
MiniMax H3 is the model that reshaped the value ladder in 2026. It is the only one of the three released as open weights, it pushes 2K resolution, and it accepts up to twelve reference inputs at once for identity, action, scene, and sound.
The reference system is H3's real differentiator for storytelling work. Instead of a single image anchor, you can hand it separate references for a character's face, a body or costume, a background, a camera move, and even a voice or ambient track. The model then binds those references across a 5 to 15-second clip, which is what makes it strong for serialized content where a character has to stay recognizable from shot to shot. Independent YouTube creator tests reviewed for this comparison consistently ranked H3 ahead of Kling 3.0 on visual detail, texture fidelity, and character motion coherence.
The trade-off is resolution ceiling. H3 tops out at 2K, so it is not the right tool for a 4K deliverable or a theatrical master. It is, however, enough for almost every vertical social format and most web playback. The native stereo audio is also notable: it is not a bolted-on text-to-speech track but a model-level audio output, which keeps sound design in the same generation pass.
H3 pricing worked example
At $0.13 per second at 2K, a finished minute of H3 footage runs about $7.80 before any failed generations. That number is the backbone of the value argument, because the same minute at Veo 3.1's premium per-second rate lands near three times that figure, which is the gap community benchmarks and AlphaSignal flagged in their July 2026 coverage.
Kling 3.0: motion transfer and 1080p output
Kling 3.0 from Kuaishou is the model to reach for when the motion itself is the asset. Its motion-transfer capability lets you supply a reference video and retarget the movement in that clip onto a new character or scene, which is something neither H3's reference system nor Veo 3.1's text-and-image pipeline does as directly.
Keep prompt, references, ratio, duration, and scoring rules stable across models. The production winner is the route that clears the shot's threshold with the least repair and operator time.
Originally published by the PixMind Editorial Team
For visual creators, a model comparison should route real shots instead of declaring one universal winner. Start with the constraint that cannot fail—cinematic ceiling, native audio, character motion,...
https://www.essentiallysports.com/wnba-basketball-news-las-vegas-aces-waive-chennedy-carter-five-hours-after-tendering-offer-sheet-to-an-indiana-fever-player/
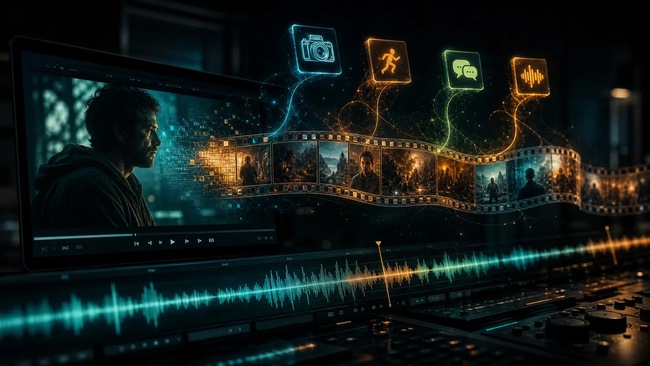
For visual creators, the best workflow is the one that preserves intent while making each decision easy to inspect and revise. This edition emphasizes those practical controls. A useful video-to-prompt workflow should preserve timing, camera language, motion, and sound while still producing text a creator can edit.
Disclosure: I work with PixMind.
By the end of this guide, you'll know exactly how to use PixMind's video-to-prompt tool to break any video — from any platform — into reusable, shot-by-shot prompts that are precisely adapted for Veo, Kling, Runway, and other leading AI video generation models.
1. What Is Video-to-Prompt? (How It Differs from Image-to-Prompt, and Why It Matters in 2026)
Video-to-prompt is the process of automatically parsing an existing video into structured AI generation prompts. It goes far beyond describing "what happens in this video" — it breaks down camera framing, shot duration, character action, dialogue pacing, and ambient sound, then outputs everything in a format that AI video models can directly consume.
Core Differences from Image-to-Prompt
Dimension Image-to-Prompt Video-to-Prompt
| Input unit | Single static frame | Multi-frame sequential shots (with timing)
| Output dimensions | Composition, style, color | Camera motion, duration, dialogue, sound
| Target models | Midjourney, Flux, DALL-E, etc. | Veo, Kling, Runway, Sora, etc.
| Information density | Single-layer description | Layered, shot-by-shot structure
| Temporal information | None | Present (Shot 1 → Shot 2 → Shot N)
Why It's Especially Valuable in 2026
AI video generation quality has improved dramatically, but prompt quality remains the single biggest variable determining output results. The problem most creators face isn't a lack of vision — it's the inability to translate that vision into precise cinematographic language.
Video-to-prompt solves exactly that translation problem. You don't need to memorize cinematography terminology from scratch. Find a reference video that captures the feeling you're after, and the tool converts it into structured language that AI models understand.
For YouTube Shorts creators, brand video teams, and independent filmmakers, this means being able to systematically replicate the shot logic of high-performing videos — rather than guessing at prompts from scratch every time.
2. How to Extract Prompts from a Video: A Four-Step Workflow
PixMind's video-to-prompt tool accepts two types of input: direct video file upload, or a pasted video URL. Here's the complete workflow.
Step 1: Upload a File or Paste a Link
On the tool page, you'll find two input options:
- Upload file: Supports common local video formats (MP4, MOV, WebM, etc.)
- Paste URL: Directly paste a video link from YouTube, TikTok, Instagram, Xiaohongshu, Douyin, Bilibili, and other platforms
Note: When pasting a URL, make sure the video is publicly accessible. Private videos or content that requires login cannot be parsed.
Step 2: Select Your Target Generation Model
The tool outputs optimized prompt formats for different AI video models. Before extracting, select your target model (Veo, Kling, Runway, etc.) — the prompt structure and phrasing style will adjust accordingly.
This step matters more than it might seem. The same shot described for Veo works differently than one written for Kling. Veo favors natural narrative prose; Kling responds better to precise action descriptions; Runway is most sensitive to camera motion parameters.
Step 3: Extract Shot-by-Shot Prompts
Once extraction is complete, the tool outputs a structured prompt sequence organized by shot number. Each shot contains four elements:
Element What It Covers Example
| Camera | Framing, angle, focal length feel | close-up, eye-level, wide shot
| Motion | Camera movement type | slow dolly in, pan left, static
| Dialogue | Character speech content and emotional tone | "Let's go," casual and upbeat
| Sound | Ambient audio, background music atmosphere | urban street ambience, low-frequency rhythmic pulse
Step 4: Refine and Reuse
The extracted prompt is a starting point, not a finished product. Recommended refinement directions:
- Swap the subject: Replace the original video's people or settings with your own brand elements
- Adjust duration parameters: Modify per-shot length to match your target platform (Shorts / Reels / TikTok)
- Reinforce style language: Add style modifiers after the Camera description (cinematic, documentary, lo-fi, etc.)
- Remove irrelevant shots: Extraction results may include transitional shots — trim as needed
If you need a full script rather than individual prompts, pair this tool with the video-to-script tool — the two complement each other well.
3. Platform-by-Platform Differences in Video-to-Prompt Extraction
Different platforms have distinct narrative rhythms, aspect ratios, and content logic. Your extraction strategy should adapt accordingly.
YouTube / YouTube Shorts
Long-form YouTube videos have a slower shot rhythm — individual shots typically run 3–8 seconds, making them well-suited for extracting narrative-rich scene descriptions. YouTube Shorts moves much faster, with shots often lasting just 1–2 seconds; focus your attention on the Motion element (quick cuts, jump cuts).
Extraction tip: For Shorts content, zero in on the hook shot in the first 3 seconds. Save the Camera + Motion description for that opening shot separately — it becomes a reusable opening template for your own videos.
TikTok / Douyin
TikTok and Douyin viral videos rely heavily on rhythm and close-up framing of people. In the extracted prompts, the Dialogue element tends to be the most critical — a lot of TikTok success comes from how someone speaks, not just what's on screen.
Extraction tip: Pay close attention to the Sound element's beat descriptions. TikTok shot cuts are often tightly synced to music, and preserving that timing relationship in your prompt is key.
PixMind has a dedicated in-depth guide on TikTok video-to-prompt — worth reading if that's your primary platform.
Instagram Reels / Facebook Reels
Instagram Reels places a higher premium on visual aesthetics. Color grading information will surface in the Camera descriptions of your extraction results (e.g., warm tones, desaturated look).
Extraction tip: Pull the color tone information from the Camera descriptions and apply it as a unified visual style keyword across your entire series of prompts — this keeps your account's visual identity consistent.
Xiaohongshu
Xiaohongshu video content centers on lifestyle and product discovery, with a shooting style that leans natural and handheld. Extracted Motion descriptions will often include terms like handheld and slight shake — these work well for generating authentic-feeling content in Veo.
Extraction tip: The cover frame on Xiaohongshu videos is usually the most carefully composed shot. Extract the Camera description for that single frame and use it directly for AI image generation (pair it with the AI image generator).
Bilibili
Bilibili spans a wide range of content types — VLOGs, educational explainers, AMVs, and more. Identify the video type before extracting:
- VLOG content: Prioritize Motion + Sound; these videos are narrative-driven
- Educational / explainer content: Dialogue is the most important element; Camera is often static
- AMV / remix content: Motion rhythm is the core; Sound descriptions need to specify music genre precisely
Kuaishou / Pinterest / Snapchat / X / Threads
Videos on these platforms tend to be short and format-diverse. The best extraction strategy here is single-shot highlight extraction — don't chase a complete sequential shot list. Instead, identify the 1–2 most reference-worthy shots and pull their Camera + Motion descriptions.
4. Which Model Should You Target with Your Extracted Prompt?
Extracted prompts aren't universally interchangeable — different AI video generation models have distinct "language preferences." Here's how to adapt for each major model.
Veo (Google)
Veo excels at understanding natural narrative language. Rather than stacking fragmented keywords, integrate the four extracted elements into smooth, paragraph-style descriptions.
Adaptation priorities:
- Merge Camera + Motion into a single flowing sentence ("The camera begins at a distance and slowly pushes in over three seconds, settling into a close-up on the subject's face")
- Be specific with Sound — Veo reproduces ambient audio well
- Dialogue can be written directly into the prompt; Veo supports speech generation
Less suited for: Ultra-short shots (<1 second) in rapid-cut sequences. Veo performs best with smooth, continuous camera movement.
Kling
Kling is more sensitive to precise action and physical descriptions. Write the Motion element with as much specificity as possible.
Adaptation priorities:
- Quantify Motion descriptions ("pan left approximately 30 degrees" outperforms "move left")
- Break character action down to the limb level
- Include depth-of-field information in Camera descriptions (shallow depth of field, bokeh background)
Less suited for: Overly abstract emotional descriptions. Kling responds to concrete physical action language.
Runway
Runway is the most sensitive of the three to camera motion parameters — and the most cinematic in its output.
Adaptation priorities:
- Write the Camera element in the most detail, including lens type (35mm, 85mm, etc.)
- Use professional cinematography terminology in Motion descriptions (dolly zoom, rack focus, whip pan)
- State shot duration explicitly ("4-second shot")
Less suited for: Dialogue-driven scenes. Runway's lip-sync and speech generation capabilities are comparatively limited.
Sora / Other Models
Sora-style models typically demand strong world coherence and physical consistency. When adapting prompts for these models, add more scene context to the Camera element — make sure the AI understands the full spatial relationship, not just the action within a single shot.
5. Prompt Quality Techniques: The Four-Element Framework in Detail
Raw extracted prompts almost always need human refinement. Here are the writing standards for each element, along with common low-quality counterexamples.
Camera Element
High-quality example:
Wide establishing shot, slightly high angle,
natural morning light from the left,
shallow depth of field with background softly blurred.
Low-quality counterexample:
A person standing on a street
The problem: no framing, angle, or lighting information. The AI has no way to reconstruct the intended shot.
Motion Element
High-quality example:
Camera starts static, then slowly dollies in over 3 seconds,
ending in a medium close-up on the subject's hands.
No shake, smooth movement.
Low-quality counterexample:
The camera moved a bit
The problem: no direction, speed, or start/end state. The AI will generate random movement.
Dialogue Element
High-quality example:
Subject says: "今天是个好日子" — tone: warm, slightly excited,
natural speaking pace, no dramatic pause.
Low-quality counterexample:
The character said something
The problem: no specific content or emotional annotation. Dialogue output becomes completely unpredictable.
Sound Element
High-quality example:
Ambient: busy coffee shop background noise,
low hum of espresso machine, occasional chatter.
No music. Sound level: moderate.
Low-quality counterexample:
There's some background sound
The problem: no sound type or layering. The AI can't distinguish between music, ambient audio, and sound effects.
Combined Four-Element Prompt Template
A complete shot-by-shot prompt template you can copy and adapt:
Shot [N] | Duration: [X] seconds

Camera: [framing] + [angle] + [lighting conditions] + [depth of field]
Motion: [starting state] → [movement type] → [ending state], [speed description]
Dialogue: "[exact line]" — tone: [emotion], pace: [speaking speed]
Sound: [ambient sound type], [music presence and genre if any], level: [volume]

Style note: [overall style keywords, e.g. cinematic / documentary / lo-fi]
Pre-Submission Quality Checklist
Before feeding your prompt to a model, run through this checklist:
- [ ] Does Camera specify framing (wide / medium / close-up)?
- [ ] Does Motion include direction and speed?
- [ ] If characters speak, does Dialogue include the exact line and emotional tone?
- [ ] Does Sound distinguish between ambient audio and background music?
- [ ] Is overall shot duration specified?
- [ ] Is the prompt aligned with the target model's style preferences (see Section 4)?
- [ ] Are there any irrelevant style keywords crammed in? (Avoid stuffing every adjective you can think of)
6. FAQ: 5 Common Questions About Video-to-Prompt
Q1: What video formats are supported?
File upload supports common formats including MP4, MOV, and WebM. URL input supports publicly accessible videos from YouTube, TikTok, Instagram, Xiaohongshu, Douyin, Bilibili, Kuaishou, Pinterest, Snapchat, X, Threads, Facebook, and more. Check the tool page for the most current list of supported platforms and formats.
Q2: Can free users access this feature?
PixMind operates on a Freemium model. Free users can try the video-to-prompt feature with a usage limit. For bulk extraction or longer videos, upgrading to a subscription plan is recommended.
Q3: Which platforms does the tool cover?
The current platform matrix includes: YouTube / YouTube Shorts, TikTok, Instagram Reels, Facebook Reels, X (Twitter), Threads, Pinterest, Snapchat, Xiaohongshu, Douyin, Bilibili, and Kuaishou — 11+ major platforms in total.
Q4: Which AI video generation models can I use the extracted prompts with?
Extracted prompts can be adapted for Veo (including Veo 3.1), Kling, Runway, Sora, and other leading models. The tool lets you select a target model before extraction, and the output format adjusts accordingly. That said, we still recommend applying the model-specific refinements covered in Section 4.
Q5: How accurate is the extraction?
Extraction quality depends on multiple factors: source video resolution, shot complexity, and platform-level video compression. For videos with clear footage and well-defined cuts, results are generally strong. For rapid-edit sequences, heavy visual effects, or low-quality source footage, treat the extracted output as a structural reference and manually fill in key details. We don't cite specific accuracy figures here — real-world results will vary based on your use case.
Closing Thoughts
Video-to-prompt isn't magic — it's a systematic tool for translating "feeling" into "language." Master the four-element framework (Camera / Motion / Dialogue / Sound), develop an understanding of how different platforms shape content logic, and adapt your output to the preferences of your target model. Do all three, and you can turn any reference video's shot logic into a reusable AI generation asset.
Start with the PixMind video-to-prompt tool. Upload a video that captures the feeling you're after, and see what's actually driving its visual language.
Save the strongest result together with its prompt structure and reference choices. That small archive becomes far more useful than a gallery with no record of how the work was made.
Originally published by the PixMind Editorial Team https://www.pixmind.io/posts/video-to-prompt-complete-guide-2026
For visual creators, the best workflow is the one that preserves intent while making each decision easy to inspect and revise. This edition emphasizes those practical controls. A useful video-to-promp...
This adapted edition is organized for ecommerce operators who need a repeatable production workflow, not a model showcase. It focuses on listing requirements, reference fidelity, prompt structure, and the point at which a studio still earns its cost.
Disclosure: I work with PixMind. The selection framework is platform-neutral; the original PixMind article and source notes are linked below.
An AI product photo generator takes a real product shot, a 3D render, or a written brief and returns listing-ready studio imagery. You skip the photographer booking. Output covers white background, controlled lighting, lifestyle scene, or model try-on. In 2026 a typical AI-produced product image costs $2–$3, against industry-estimated $55–$160 for traditional studio output, an 80–97% reduction (Hailuo AI, 2026; iGenUltra, 2026). For an ecommerce operator, that changes how you produce the 6–9 images Amazon expects per listing, not whether you produce them.
This guide covers what an AI product photo generator does and which 2026-era models handle product work best. It also covers how to write prompts that pass Amazon and Shopify review. Disclosure: PixMind ships a Product Image tool. The model-by-model claims below draw on official model documentation, vendor announcements, and community testing. They are not a PixMind benchmark of every model on every category. Announced-but-unverified capabilities are hedged.
Key Takeaways
- AI product photos cost ~$2–$3 per image vs. $55–$160 for studio shoots, an 80–97% reduction (Hailuo AI, 2026).
- Listings with AI-edited product images convert up to 2.8× higher than raw smartphone photos in industry-cited research (Rewarx, 2026).
- GPT-Image-2, Nano Banana Pro (Gemini 3 Pro Image), Midjourney v7, Seedream 5.0 Pro, and Flux Kontext Pro each win a different slice of product work — there is no single best model.
- Amazon's main image rule is pure white RGB 255,255,255, product filling 85–100% of frame, no props, no text — design prompts around that from the start.
What an AI Product Photo Generator Actually Does
An AI product photo generator is not the same tool as a general image model. The general model takes a text prompt and invents pixels. A product photo generator is built around a real input image of your product and protects it through the edit. The bottle, label, and proportions stay identical while the background, lighting, and context change.
The core jobs are narrow and concrete. Swap a kitchen-counter snapshot to pure white. Restage the same SKU onto marble, sand, or a holiday table. Composite a garment onto a model. Render packaging mockups before the physical box exists. Each of those used to be a separate shoot, and each is now one prompt. The output is held to an ecommerce standard — typically 1024×1024 minimum, often 2048×2048 or native 4K, with legible text on labels and packaging.
[ORIGINAL DATA] On PixMind, product-photo prompts are the dominant ecommerce use case across the AI Apps workspace, ahead of general marketing creative (PixMind internal prompt logs, 2026-07). Common phrasings include product photo on white background, studio product shot, and lifestyle product scene. That matches the wider industry pattern: product imagery, not ad copy, is where AI image generation actually ships.
The category overlap with adjacent tools is worth separating. virtual try-on composites garments on models. Product mockups place artwork on physical substrates; marketing posters layer typography over an image. A product photo generator sits upstream of all three — it produces the clean hero those workflows consume.
Why Ecommerce Teams Moved to AI Product Photos in 2026
The economics forced the shift. A full professional product shoot in 2026 runs $4,750–$20,000 once you factor studio, photographer, retoucher, props, and talent (TAMEYO Group, 2026). Per-image, that lands at $25–$500, with retouching adding ~$30 per frame on top (Nightjar, 2026). Against that baseline, $2–$3 per AI image is not a discount — it is a different category of spend.
The quality gap closed at the same time. Listings built on high-resolution product photos convert roughly 94% better than low-resolution alternatives (GrabOn, 2026). Industry-cited research also reports AI-edited product images convert up to 2.8× higher than raw smartphone photos (Rewarx, 2026). Survey work puts the indistinguishability rate at around 83%. Four in five shoppers cannot reliably tell an AI product image from a studio one (Rajat AI, 2026). That number is not a license to fabricate, but it does mean the output no longer reads as obviously synthetic.
[PERSONAL EXPERIENCE] From running product-image prompts across models on PixMind, the practical takeaway is that the bottleneck has moved off generation cost and onto brief clarity. The teams that win arrive with a brand style guide, a lighting reference, and a written definition of done. The teams that struggle chase the model with adjectives.
Which AI Product Photo Generator Models Fit Each Job
There is no single best product-photo model in 2026. The five worth comparing split along text handling, edit fidelity, lighting aesthetics, and reference-image control.
GPT-Image-2 is the safest pick when the product has text on it — labels, packaging, embossed logos, multilingual typography. Community and vendor testing reports near-perfect text rendering on packaging mockups, realistic shadows and reflections, and reliable label reproduction (Masonry, 2026; MindStudio, 2026; OpenAI, 2026). Weak spot: conservative on stylized scene composition. try GPT-Image-2 for product shots.
Nano Banana Pro (Gemini 3 Pro Image) is Google's 4K-capable image model. Based on announced capabilities, it leads for legible on-image text and intricate diagrams (Google DeepMind, 2026; Google Blog, 2026; Engadget, 2026). It accepts up to 14 reference input images. That suits multi-angle product briefs where you want consistent SKU identity across hero, detail, and lifestyle frames.
Midjourney v7 is the pick when the goal is advertising-grade aesthetics — soft studio diffusion, lens character, surfaces that read as expensive. Community prompt guides report v7 parameters give reliable studio-lighting control with fragments like studio lighting, product photography, soft diffused light, clean background (The Right GPT, 2026; AI Tuts, 2026). Weak spot: weaker text rendering than GPT-Image-2 or Nano Banana.
Seedream 5.0 Pro from ByteDance Doubao ships native 4K and interactive precise editing. Draw an arrow or circle and the model edits just that region (ByteDance Seed, 2026; Sina Finance, 2026). API pricing near $0.043 per request matters at catalog scale (302.ai, 2026). Strongest pick for Chinese-market listings and teams that need local-region edits without re-running the whole prompt.
Flux Kontext Pro from Black Forest Labs is the editing specialist. Feed it a reference image and a text instruction and it performs targeted local edits. It swaps a background, changes a surface, or fixes a label without regenerating the product (Black Forest Labs, 2026; fal.ai, 2026). Use it when you have a usable hero shot and need ten regional variants, not when starting from a blank prompt.
Model Best for Key strength Watch out
| GPT-Image-2 | Packaging, labels, multilingual text | Near-perfect text rendering | Conservative on stylized scenes
| Nano Banana Pro (Gemini 3 Pro Image) | Multi-angle briefs, 4K hero shots | Up to 14 reference images, 4K output | Newer, fewer community workflows
| Midjourney v7 | Advertising-grade aesthetics | Studio-lighting control via prompt | Weaker text on labels
| Seedream 5.0 Pro | Regional edits, Chinese-market listings | Native 4K, interactive precise editing | Less adoption outside APAC
| Flux Kontext Pro | Local edits on existing shots | Reference-image + text-instruction editing | Not a from-scratch generator
[UNIQUE INSIGHT] The five-model comparison hides a workflow truth: production teams rarely pick one. A realistic 2026 stack pairs GPT-Image-2 or Nano Banana for the packaging hero, Midjourney v7 for the lifestyle spread, Flux Kontext for A/B-test background variants. Forcing one model across all four jobs is the most common failure mode in prompt logs.
How to Generate a Product Photo That Meets Amazon and Shopify Rules
Amazon's main image rule is the strictest in ecommerce and the right default to design around. The main image must use a pure white background at exactly RGB 255, 255, 255. The product must fill 85–100% of the frame, and props, text overlays, watermarks, and lifestyle settings are prohibited (Amazon Seller Central, 2026; SellerLabs, 2026). Files need at least 1,000 pixels on the longest side for zoom, with 72 dpi minimum (Amazon Seller Forums, 2026). Light grey or "studio white" fails review — Amazon checks the hex value (UsePixora, 2026).
The workflow below produces an Amazon-compliant main image and the lifestyle secondaries that go alongside it.
Step 1: Prepare the source. Use the cleanest possible input — a flat-lit phone shot on a neutral surface works, a 3D render works better. The model needs the product's true proportions and label. Crop loosely; do not pre-clean the background.
Step 2: Lock the product, free the background. Use a model that takes a reference image (Flux Kontext, Nano Banana, Seedream 5.0 Pro). The SKU does not drift between variants. Instruction: keep the product identical, replace the background with pure white RGB 255 255 255.
Step 3: Write the prompt for compliance, then aesthetics. A working Amazon main-image prompt pattern:
Studio product photograph of [PRODUCT], pure white background RGB 255 255 255,
product filling 90% of frame, centered, soft top-down lighting, no props,
no text overlay, sharp focus, high resolution, photorealistic.
For a lifestyle secondary, the constraints loosen — props, context, and human hands are allowed — and the prompt shifts to scene work:
[PRODUCT] on a marble kitchen counter, morning window light from the left,
shallow depth of field, lifestyle ecommerce photography, no people,
photorealistic, 2048x2048.
Step 4: Upscale and QA. Most generators output 1024×1024 or 2048×2048. If the longest side is under 1,000 pixels, run an AI upscaler before upload. Then QA three things: background samples as pure white, label text is legible at 100% zoom, and the product fills 85–100% of the frame.
Step 5: Batch the variants. Once the hero frame is locked, use the same reference image with different background instructions. That produces the 6–9 images a full Amazon listing expects — lifestyle, scale, detail, packaging, infographics. The reference-image workflow is what keeps the SKU consistent across the set.
For Shopify, pure white is encouraged but not enforced, so the Amazon-compliant version ports straight over. Etsy, Walmart, and TikTok Shop sit between the two; design for Amazon and you are covered.
remove backgrounds from existing photos
Common Product Photo Jobs and How to Brief Them
Most product photo requests collapse into four job types. Briefing by job type — rather than by aesthetic moodboard — is what gets consistent output across models.
Pure-white main image. Goal: pass Amazon review, show product clearly. Brief: pure white RGB 255,255,255 background, product fills 90% of frame, soft top-down lighting, no props. Best models: Flux Kontext or Seedream 5.0 Pro for the reference-image edit, GPT-Image-2 if the label has text.
Lifestyle scene. Goal: show product in use, secondary image slot. Brief: specific environment (marble counter, oak desk, linen bedsheets), light direction, depth of field, no people unless requested. Best model: Midjourney v7 for aesthetic, Nano Banana for text-safe scenes.
Model try-on. Goal: garment, accessory, or beauty product on a person. Brief: model description, pose, garment fidelity (preserve exact print and stitching), diverse body types across the set. Use a dedicated try-on pipeline — Try-On handles garment compositing. Do not imply a brand endorsement when the brand is not yours.
Marketing creative. Goal: ad asset, social post, hero banner. Brief: campaign concept, brand colors, typographic hierarchy, headline placement. Best models: Nano Banana or GPT-Image-2 for the image, handed off to Marketing Poster for layout.
A note on hedging: across these four jobs, AI is reliably better than a studio only for the pure-white main image, because the constraints are mechanical. Lifestyle and try-on are competitive but not always superior — fabric drape, glossy reflections, and scale accuracy still trip current models. Do not claim in your listing that an AI image is a photograph if your jurisdiction's ad rules require disclosure.
Where AI Product Photos Still Lose to a Studio
The honest case for a studio still exists. AI product photo generators in 2026 struggle with four categories, and knowing them prevents wasted prompt iterations.
Complex reflective surfaces. Chrome, glass, faceted jewelry, polished ceramics depend on controlled reflections shaped intentionally by studio lights. AI models approximate the look but sample inconsistently across the surface. For a luxury watch or perfume flacon hero, the studio still wins.
Exact color matching. Brand reds and Pantone-linked product colors require precise colorimetry. AI output drifts half a shade under different lighting prompts. If the brand guideline specifies Pantone 185 C, plan for a color-correction pass after generation.
Fabric drape and fit. Structured tailoring, sheer fabrics, and knit elasticity still read slightly off when AI-generated. Try-on models narrow the gap but do not close it. For a flagship apparel launch, the studio remains the source of truth.
Real people and real endorsement. AI composites of identifiable people run into likeness and disclosure rules. When the campaign depends on a real person, the studio is the legal path, not just the aesthetic one.
The practical split: AI for catalog-scale imagery (white-bg, lifestyle secondaries, marketing variants) and studio for hero campaign work (brand-critical launches, talent-led shoots, reflective or color-sensitive product).
Frequently Asked Questions
What is an AI product photo generator?
It is a tool that takes an existing product image, 3D render, or brief and produces studio-grade listing photography. Output covers a pure-white main image, lifestyle scene, or model composite. In 2026 it costs roughly $2–$3 per image, against $55–$160 for a studio equivalent (Hailuo AI, 2026).
Can AI product photos pass Amazon review?
Yes, if the main image uses a pure white RGB 255,255,255 background and the product fills 85–100% of the frame. Props, text, and watermarks must be absent (Amazon Seller Central, 2026). Most 2026-era models hit those specs when prompted explicitly.
Which AI model is best for product photos?
There is no single winner. GPT-Image-2 leads on label and packaging text. Nano Banana Pro (Gemini 3 Pro Image) leads on 4K output and multi-angle reference. Midjourney v7 leads on advertising aesthetics. Seedream 5.0 Pro and Flux Kontext lead on regional edits to an existing shot.
Are AI product photos legal for ecommerce listings?
In most jurisdictions, yes, with two caveats. Disclose when an image materially misrepresents the product, and do not composite identifiable real people or imply brand endorsements that do not exist. Check local ad standards — the US FTC and EU consumer protection rules both treat misleading product imagery as a compliance issue.
How much does an AI product photo cost vs. a studio shoot?
An AI-generated product image runs $2–$3 in 2026; a studio shoot runs $4,750–$20,000 per session or $25–$500 per image (TAMEYO Group, 2026; Nightjar, 2026). The cost case for AI is overwhelming at catalog scale. The studio case survives at brand-hero scale where reflective surfaces, color match, or real talent matter.
Wrapping Up
The right way to use an AI product photo generator in 2026 is as a catalog-scale production tool, not a studio replacement. Pick the model by job type: GPT-Image-2 or Nano Banana for text-heavy packaging, Midjourney v7 for aesthetic lifestyle spreads, Flux Kontext or Seedream 5.0 Pro for reference-image edits. Design every prompt around Amazon's pure-white main-image rule so the output ports across marketplaces. Reserve the studio for hero campaign work where reflection, colorimetry, or real people are load-bearing.
The teams getting this right are not the ones chasing a single best model. They are the ones with a written definition of done, a fixed brand style guide, and a reference-image-first workflow that keeps the SKU identical across every variant.
Start with the Product Image tool for the white-bg main image. Layer Marketing Poster once the listing expands into paid social.
Sources
- Hailuo AI, AI Product Photos: The 2026 Guide to Studio-Free Images, retrieved 2026-07-19, https://hailuoai.video/pages/blog/ai-product-photography-guide
- iGenUltra, AI Product Photography 2026: Studio Quality Without the Cost, retrieved 2026-07-19, https://www.igenultra.com/blog/ai-product-photography-tools-2026
- Nightjar, The Real Cost of Product Photography in 2026: A Breakdown, retrieved 2026-07-19, https://nightjar.so/blog/the-real-cost-of-product-photography-a-breakdown
- TAMEYO Group, AI Photoshoot vs Professional: 2026 Costs, retrieved 2026-07-19, https://www.tameyogroup.com/post/ai-generated-vs-professional-photoshoots
- Rewarx, AI Product Photography Statistics 2026, retrieved 2026-07-19, https://www.rewarx.com/blogs/ai-product-photography-statistics-ecommerce-2026
- GrabOn, 53 Crucial Ecommerce Product Photography Statistics (2026), retrieved 2026-07-19, https://grabon.com/blog/product-photography-statistics/
- Rajat AI, AI Product Photography Tools 2026: Cost & Workflow, retrieved 2026-07-19, https://rajatgautam.com/blog/ai-product-photography-guide-2026/
- Photta, The State of AI Product Photography in 2026, retrieved 2026-07-19, https://www.photta.app/blog/state-of-ai-product-photography-2026
- WiseGuy Reports, AI Product Photography Tool for E-Commerce Market 2035, retrieved 2026-07-19, https://www.wiseguyreports.com/reports/ai-product-photography-tool-for-e-commerce-market
- Amazon Seller Central, Product Image Guide, retrieved 2026-07-19, https://sellercentral.amazon.com/help/hub/reference/external/G1881
- SellerLabs, Amazon Product Image Requirements 2026, retrieved 2026-07-19, https://www.sellerlabs.com/blog/amazon-product-image-requirements-2026/
- UsePixora, Amazon Product Image Requirements 2026: Main Image Checklist, retrieved 2026-07-19, https://www.usepixora.com/resource/amazon-compliance-guide
- OpenAI, Introducing ChatGPT Images 2.0, retrieved 2026-07-19, https://openai.com/index/introducing-chatgpt-images-2-0/
- Masonry, GPT Image 2: Why It's the Most Reliable AI Model for Product and Brand Photography, retrieved 2026-07-19, https://masonry.so/blog/gpt-image-2-guide
- MindStudio, GPT Image 2: 10 Practical Use Cases for Businesses and Creators, retrieved 2026-07-19, https://www.mindstudio.ai/blog/gpt-image-2-use-cases
- Google DeepMind, Gemini 3 Pro Image — Nano Banana Pro, retrieved 2026-07-19, https://deepmind.google/models/gemini-image/pro/
- Google Blog, Introducing Nano Banana Pro, retrieved 2026-07-19, https://blog.google/innovation-and-ai/products/nano-banana-pro/
- Engadget, Google's Nano Banana Pro image generator leverages Gemini 3, retrieved 2026-07-19, https://www.engadget.com/ai/googles-nano-banana-pro-image-generator-leverages-gemini-3-for-improved-visuals-and-text-rendering-185505073.html
- The Right GPT, Midjourney Prompts for Product Photography, retrieved 2026-07-19, https://therightgpt.com/midjourney-prompts-for-product-photography/
- AI Tuts, Midjourney Prompts for Product Photography & Design, retrieved 2026-07-19, https://aituts.com/midjourney-product-photography/
- ByteDance Seed, Seedream 5.0 Pro 发布, retrieved 2026-07-19, https://seed.bytedance.com/zh/blog/beyond-generation-it-understands-design-introducing-seedream-5-0-pro
- Sina Finance, 豆包图像创作模型 Seedream 5.0 Pro 发布, retrieved 2026-07-19, https://finance.sina.com.cn/tech/roll/2026-06-23/doc-iniekqur9761230.shtml
- 302.ai, doubao-seedream-5-0-pro-260628 — API 价格、文档与测评, retrieved 2026-07-19, https://302.ai/product/detail/doubao-seedream-5-0-pro-260628
- Black Forest Labs, Image Editing — FLUX.1 Kontext Documentation, retrieved 2026-07-19, https://docs.bfl.ml/kontext/kontext_image_editing
- fal.ai, FLUX.1 Kontext [pro] API, retrieved 2026-07-19, https://fal.ai/models/fal-ai/flux-pro/kontext
Originally published by the PixMind Editorial Team: AI Product Photo Generator: Complete Guide for Ecommerce.
This adapted edition is organized for ecommerce operators who need a repeatable production workflow, not a model showcase. It focuses on listing requirements, reference fidelity, prompt structure, and...
Invoice templates streamline billing, reduce errors, save time, and enhance professionalism for your business.
Invoicing is an essential part of every business, but it often goes unnoticed.
Fortunately, a wide variety of free invoice templates are available online, making it easier for businesses from all industries to streamline their billing process.
By using these free templates, an effective financial management system can be built, saving valuable time and resources while simplifying the invoicing process.
For freelancers and skilled professionals, workload efficiency is enhanced, and business operations are refined, both of which are critical to success. A smooth and efficient billing process is considered a fundamental element in achieving these objectives.
Although initially daunting, the implementation of this strategy is made effortless with the use of widely available tools, such as blank invoice templates. This allows superior services to be provided to clients while pending payments are continuously monitored.
By leveraging these invoicing templates, greater focus can be placed on the primary activities driving the business forward, ensuring long-term growth and prosperity.
The key benefits of adopting blank invoice templates will be explored, as they improve billing practices and guide your firm toward greater success.
To start, we’ll first explore the concept of an invoicing template.
An invoice template is referred to as a document used by businesses and individuals to generate professional invoices for the goods or services provided to customers or clients.
Predefined fields, formats, and designs are included, allowing relevant details, such as descriptions, quantities, prices, taxes, discounts, shipping costs, payment terms, due dates, and other necessary data, to be easily entered.
A ready-made invoice template is used as a guide or framework to ensure consistency and accuracy across multiple transactions. A polished image can be projected by organizations, and customer satisfaction can be improved by standardizing the appearance and content of invoices.
Additionally, tracking of income, expenses, and outstanding balances is made easier for bookkeepers and accountants, as all documents are aligned with a set format.
Various types of invoice templates are offered in different file formats, including Microsoft Word, Excel, Google Sheets, Adobe Acrobat PDF, and more. Premade templates can be downloaded, or customized versions can be created to suit specific business needs.
The Benefits of Using an Invoice Template
An invoice template (primarily the PDF invoice template) is considered essential for both small and large businesses in managing finances and maintaining proper records. As the benefits of invoice templates continue to be explored, several reasons are given for why companies opt to use invoice templates or invoice template software:
- Invoice templates ensure consistency in the appearance and format of invoices, making them easily recognizable and understandable. This uniformity guarantees that important information is never unintentionally left out of an invoice.
- By using an invoice template, the need to start from scratch each time an invoice is generated is eliminated. Instead, necessary details can be quickly filled in, allowing a professional-looking document to be produced in just minutes.
- An invoice template reduces the risk of human error in calculating figures, applying taxes, or including discounts. Built-in formulas and fields automatically manage these calculations, leaving minimal room for mistakes.
- Invoice templates can be customized to incorporate your company logo, colors, and branding elements, reinforcing your corporate identity and building trust among clients.
- Invoice templates are designed to be integrated with accounting software, allowing for seamless data transfer between systems. This integration reduces the burden of manual data entry, streamlines account receivables, and keeps financial records organized.
- Flexible options for items, pricing, taxes, discounts, and other variables are offered by many free invoice templates, allowing them to be adapted to your business needs.
In conclusion, invoice templates, such as those offered by InvoiceTemple, provide businesses with a streamlined, accurate, and consistent invoicing process. They save time, reduce errors, and enhance professionalism, whether you're a freelancer or a large organization.
With customizable options and integration with accounting software, invoice templates help maintain financial organization and improve client relationships, supporting long-term business success.
Invoice templates streamline billing, reduce errors, save time, and enhance professionalism for your business.
Invoicing is an essential part of every business, but it often goes unnoticed.
Fortunately,...
- The curious case of retro demo scene graphics
original article — hacker news - ChatGPT won't let you type until Cloudflare reads your React state
original article — hacker news - VHDL's Crown Jewel
original article — hacker news - Copilot edited an ad into my PR
original article — hacker news - Voyager 1 runs on 69 KB of memory and an 8-track tape recorder
original article — hacker news - 15 Years of Forking
original article — hacker news - Coding Agents Could Make Free Software Matter Again
original article — hacker news - Philly courts will ban all smart eyeglasses starting next week
original article — hacker news - C++26 is done ISO C++ standards meeting, Trip Report
original article — hacker news - Hardware Image Compression
original article — hacker news
- The curious case of retro demo scene graphics
original article — hacker news - ChatGPT won't let you type until Cloudflare reads your React state
original article — hacker news - VHDL's Crown Jewel
origin...
https://www.times-standard.com/2026/03/07/business-briefs-realtors-to-have-town-hall-with-chris-rogers/
#times-standard
- Google Workspace CLI
original article — hacker news - You Just Reveived
original article — hacker news - MacBook Neo
original article — hacker news - Building a new Flash
original article — hacker news - Show HN: Poppy – a simple app to stay intentional with relationships
original article — hacker news - You need to rewrite your CLI for AI agents
original article — hacker news - AMD will bring its "Ryzen AI" processors to standard desktop PCs for first time
original article — hacker news - What Python's asyncio primitives get wrong about shared state
original article — hacker news - Something is afoot in the land of Qwen
original article — hacker news - The L in "LLM" Stands for Lying
original article — hacker news
- Google Workspace CLI
original article — hacker news - You Just Reveived
original article — hacker news - MacBook Neo
original article — hacker news - Building a new Flash
original article — hacker news - Sho...
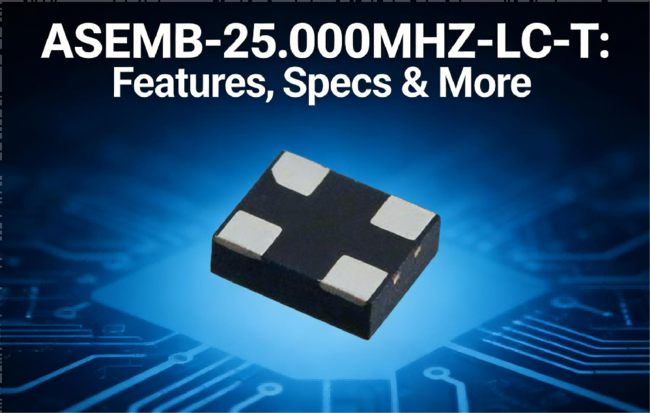
The Abracon ASEMB-25.000MHZ-LC-T is a high-performance MEMS oscillator designed for modern electronics applications. It provides a stable 25MHz clock output and ensures precision timing in demanding circuits. This device combines reliability with flexibility, making it suitable for a wide range of industrial, communication, and consumer electronics projects. With surface mount QFN packaging, it is optimized for compact PCB layouts without sacrificing performance. In this comprehensive article, we'll delve into the intricacies of the ASEMB-25.000MHZ-LC-T, uncovering its definition, key features, specifications, applications, and a closer look at its manufacturer.
ASEMB-25.000MHZ-LC-T's Overview
The ASEMB-25.000MHZ-LC-T is a MEMS clock oscillator manufactured by Abracon LLC. It produces a standard frequency of 25 MHz. Its frequency stability is rated at ±50 ppm. The oscillator is capable of operating across a wide supply voltage range of 1.8V, 2.5V, or 3.3V. It features a 4-pin QFN surface-mount package that makes it ideal for compact PCB layouts.
Key Features
Let's delve into the standout features that make the ASEMB-25.000MHZ-LC-T a standout in the world of electronics:
· The oscillator delivers a 25 MHz standard frequency for precise timing.
· It offers ±50 ppm frequency stability to maintain accuracy under various conditions.
· Frequency aging is ±5 ppm per year to ensure long-term reliability.
· The device has a 15 pF load capacitance, optimized for LVCMOS outputs.
· Maximum symmetry of the output waveform is 55% for consistent signal integrity.
· LVCMOS output levels make it compatible with modern digital logic circuits.
· It supports a wide operating temperature range from -40°C to 85°C.
· The oscillator is available in tape and reel packaging, perfect for automated assembly.
· It comes in a compact 2.5 x 3.2 mm QFN package to save PCB space.
Get more details: ASEMB-25.000MHZ-LC-T: Features, Specs & More
The Abracon ASEMB-25.000MHZ-LC-T is a high-performance MEMS oscillator designed for modern electronics applications. It provides a stable 25MHz clock output and ensures precision timing in demanding c...
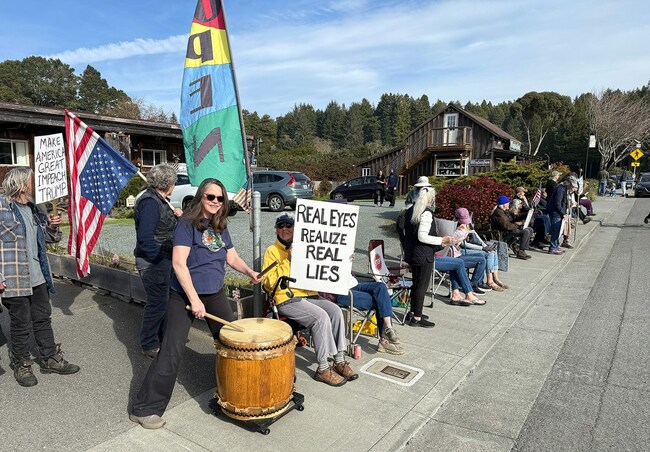
https://www.times-standard.com/2026/02/02/photo-trinidad-protests-draw-dozens-to-main-street/
#times-standard
- Prism
original article — hacker news - A few random notes from Claude coding quite a bit last few weeks
original article — hacker news - Golden Ratio using an equilateral triangle inscribed in a circle
original article — hacker news - 430k-year-old well-preserved wooden tools are the oldest ever found
original article — hacker news - Rust’s Standard Library on the GPU
original article — hacker news - Lennart Poettering, Christian Brauner founded a new company
original article — hacker news - Parametric CAD in Rust
original article — hacker news - Time Station Emulator
original article — hacker news - Doing the thing is doing the thing
original article — hacker news - There's only one Woz, but we can all learn from him
original article — hacker news
- Prism
original article — hacker news - A few random notes from Claude coding quite a bit last few weeks
original article — hacker news - Golden Ratio using an equilateral triangle inscribed in a circle
or...
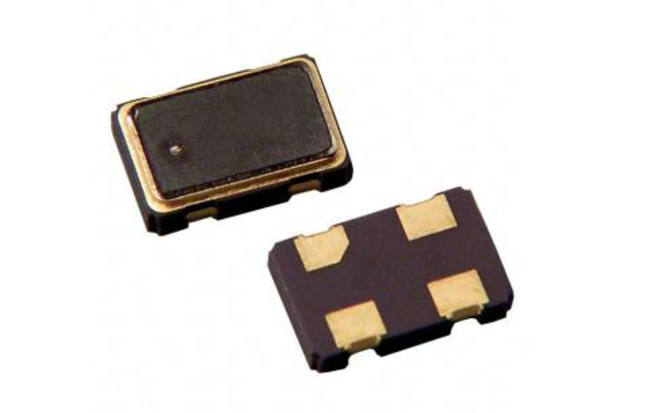
When designing modern electronic systems, frequency stability and signal integrity sit at the core of every successful architecture. The Abracon ASFL1-25.000MHZ-L-T crystal oscillator is one of those compact yet powerful timing components that engineers rely on for precision, durability, and consistent performance. In this comprehensive article, we'll delve into the intricacies of the ASFL1-25.000MHZ-L-T, uncovering its definition, key features, specifications, applications, and a closer look at its manufacturer.
ASFL1-25.000MHZ-L-T's Overview
The Abracon ASFL1-25.000MHZ-L-T is a surface-mount crystal oscillator engineered to deliver a stable 25 MHz output in compact electronic designs. It belongs to Abracon's ASFL1 oscillator family, which is known for its reliable HCMOS and TTL-compatible output, low-profile construction, and broad use across commercial, industrial, and embedded systems.
Key Features
Let's delve into the standout features that make the ASFL1-25.000MHZ-L-T a standout in the world of electronics:
· The oscillator offers ±100ppm frequency stability, ensuring consistent operation.
· It features ±5ppm aging per year, maintaining long-term accuracy.
· The load capacitance is 15pF, optimized for standard digital circuits.
· It has a maximum symmetry of 60%, delivering predictable waveform characteristics.
· The output is HCMOS/TTL compatible, allowing broad compatibility with digital ICs.
· Its operating voltage ranges from 2.97V to 3.63V, providing flexibility in design.
· The SMD 4-pin package allows compact mounting and easy assembly.
· It comes in tape-and-reel packaging, supporting automated PCB assembly.
Get more details: ASFL1-25.000MHZ-L-T: Features, Specs & More
When designing modern electronic systems, frequency stability and signal integrity sit at the core of every successful architecture. The Abracon ASFL1-25.000MHZ-L-T crystal oscillator is one of thos...
When designing high-speed electronics, choosing the right crystal oscillator is critical. The Aker Technology S5A3303-125.000-L-X-R is a precision 125MHz LVDS crystal oscillator engineered for reliable performance. In this comprehensive article, we'll delve into the intricacies of the S5A3303-125.000-L-X-R, uncovering its definition, key features, specifications, applications, and a closer look at its manufacturer.
S5A3303-125.000-L-X-R's Overview
The S5A3303-125.000-L-X-R is a crystal oscillator (XO) that generates a standard frequency of 125MHz. It is engineered to provide ±30ppm frequency stability and ±3ppm aging per year, ensuring minimal drift over time. Its output uses LVDS signaling, supporting fast and low-noise communication between high-speed electronic components. This oscillator is manufactured by Aker Technology, a trusted supplier in the electronics industry known for producing high-quality timing solutions.
Key Features
Let's delve into the standout features that make the S5A3303-125.000-L-X-R a standout in the world of electronics:
· It provides a standard frequency of 125MHz.
· Its frequency stability is ±30ppm, ensuring consistent performance.
· The frequency aging is ±3ppm per year, guaranteeing long-term reliability.
· The oscillator features a maximum symmetry of 55%.
· It outputs LVDS signals for high-speed data transmission.
· The operating voltage is typically 3.3V, with a range from 3.135V to 3.465V.
· It functions in temperatures from -40°C to 85°C.
· The oscillator is designed for surface-mount PCB installation.
· The package dimensions are 5mm x 3mm x 1.3mm, ideal for compact boards.
· It features a 6-pin configuration, supporting easy integration.
Get more details: S5A3303-125.000-L-X-R: Features, Specs & More
When designing high-speed electronics, choosing the right crystal oscillator is critical. The Aker Technology S5A3303-125.000-L-X-R is a precision 125MHz LVDS crystal oscillator engineered for relia...
https://www.times-standard.com/2025/11/10/you-and-the-law-how-to-navigate-the-legal-boundaries-of-tenant-rights-during-a-family-crisis/
#times-standard
https://www.times-standard.com/2025/11/10/you-and-the-law-ho...
https://www.times-standard.com/2025/11/03/you-and-the-law-this-is-why-judge-judy-says-details-are-important-in-contracts-this-contract-had-holes/
#times-standard
https://www.times-standa...
https://www.essentiallysports.com/nba-active-basketball-news-joel-embiid-demands-punishment-for-refs-after-nba-s-five-figure-fine-for-lewd-gesture/

https://www.essentiallysports.com/ncaa-college-football-news-pro-bowler-lost-for-words-as-ohio-states-stocks-reach-all-time-high-brian-hartline-flexes/
When it comes to reliable and efficient microcontrollers for automotive and industrial applications, the Infineon Technologies XC164CS32F40FBBAKXQMA1 stands out as a powerful choice. In this comprehensive article, we'll delve into the intricacies of the XC164CS32F40FBBAKXQMA1, uncovering its definition, key features, specifications, applications, and a closer look at its manufacturer.
XC164CS32F40FBBAKXQMA1's Overview
The XC164CS32F40FBBAKXQMA1 is a 16-bit microcontroller unit (MCU) developed by Infineon Technologies, part of the XC166 family. It uses the C166SV2 core architecture that combines CISC, DSP, and RISC instruction sets. This MCU is designed for demanding environments requiring precise control and communication capabilities, especially in automotive sectors.
Key Features
Let's delve into the standout features that make the XC164CS32F40FBBAKXQMA1 a standout in the world of electronics:
· The MCU operates at a maximum CPU frequency of 40 MHz.
· It has a 16-bit data bus width, providing efficient data handling.
· The on-chip program memory is 256KB Flash, ensuring ample space for code storage.
· It includes 12KB of RAM to support runtime operations.
· The device supports expanded memory up to 16MB, enabling extended application scope.
· Programmability is fully supported for flexible application development.
· Communication interfaces include two CAN controllers, two SPI ports, and two USART channels.
· It features 79 general-purpose I/O pins for diverse connectivity.
· There are five timers and one PWM module for timing and control.
· The MCU offers one 10-bit ADC with 14 channels for precise analog measurements.
· It includes a built-in watchdog timer and a real-time clock for system reliability.
· Operating voltage ranges from 2.35V to 5.5V, suitable for automotive power systems.
· The device withstands operating temperatures from -40°C to 125°C, meeting automotive standards.
Get more details: XC164CS32F40FBBAKXQMA1: Features, Specs & More
When it comes to reliable and efficient microcontrollers for automotive and industrial applications, the Infineon Technologies XC164CS32F40FBBAKXQMA1 stands out as a powerful choice. In this comprehen...
https://www.essentiallysports.com/nascar-news-team-boss-calls-for-new-standards-on-waiver-as-nascar-penalty-costs-richard-childress-big/
If you're designing safetycritical automotive or industrial systems, the Infineon TC275TP64F200NDCLXUMA1 is a powerful 32bit AURIX MCU. It runs at up to 200 MHz, offers 4 MB flash and 472 KB RAM. In this comprehensive article, we'll delve into the intricacies of the TC275TP64F200NDCLXUMA1, uncovering its definition, key features, specifications, applications, and a closer look at its manufacturer.
TC275TP64F200NDCLXUMA1's Overview
The TC275TP64F200NDCLXUMA1 is a 32-bit TriCore RISC-based MCU designed by Infineon Technologies. It combines performance, safety, and efficiency in one powerful package. Developed under AEC-Q100 automotive standards, it ensures long-term reliability in harsh environments, making it ideal for use in automotive control units, industrial applications, and real-time embedded systems.
Key Features
Let's delve into the standout features that make the TC275TP64F200NDCLXUMA1 a standout in the world of electronics:
· This microcontroller operates on a 32-bit TriCore™ RISC architecture that provides high-speed processing and real-time capabilities.
· It integrates 4 megabytes of embedded Flash memory, which allows for extensive program storage and reliable execution.
· This chip is equipped with 472 kilobytes of RAM, supporting efficient data handling and buffering.
· It runs at a maximum CPU frequency of 200 MHz, ensuring fast and responsive system performance.
· The device supports a wide operating voltage range from 3.0V to 5.5V, making it flexible for various power supply configurations.
· It includes 112 general-purpose input/output pins, allowing seamless integration with peripheral components and sensors.
· This MCU features a high-resolution 12-bit ADC with 40 input channels for accurate analog signal processing.
· It is built with four CAN communication interfaces, enabling reliable in-vehicle networking and data exchange.
· A dedicated watchdog timer is included to provide system safety through fault detection and recovery mechanisms.
· The device is housed in a 176-pin LQFP EP package, which supports secure and space-efficient surface mounting.
· The operating temperature range extends from -40°C to 150°C, making it suitable for harsh and automotive-grade environments.
Get more details: TC275TP64F200NDCLXUMA1: Features, Specs & More
If you're designing safetycritical automotive or industrial systems, the Infineon TC275TP64F200NDCLXUMA1 is a powerful 32bit AURIX MCU. It runs at up to 200 MHz, offers 4 MB flash and 472 KB RAM. In t...
Do you know about the further process that takes place after the client receives the product or the service? It’s issuing the invoices. While issuing the invoices, clients will experience a sense of satisfaction because they will receive payments once they forward the invoices to the clients.
How can you get timely payments? The answer is simple — include the correct due date on your invoices. However, if the invoice due date is not specified, then how does the client know about the due date and make the payment?
So, mentioning the invoice due date in the invoice is crucial. There are some tips and tricks for setting this invoice due date and some best practices for setting it. This blog mentions all the details about the invoice due date. So, continue to read and gain valuable information from this for your business.
What Does an Invoice Due Date Mean?
The invoice due date is the date that is mentioned in the invoice to disclose to the clients about the date on which or before they must make the payment. When the clients don’t make the payment within the due date, then penalties can be charged against them.
An example of this situation is as follows. A client is purchasing a computer from you, and it is delivered to the client on May 1st. Once the client receives the product, you generate the invoice for the purchased item and mention the invoice amount as $470, apply the net 90 payment term, and enter the invoice due date as July 29th. This invoice indicates that your client must make the payment on July 29th. If payment is not made on the due date, then late penalties can be charged to the client.
While mentioning the invoice due date, some factors should be considered. The first factor to be considered is the size of the business. If the business is small scaled or medium, or a startup, then net 15 and 30 payment terms can be offered. For large enterprises, net 60 and 90 payment terms can be offered. The next factor to be considered is the payment history of the clients. By considering these factors, the invoice due date can be mentioned.
Significance of Invoice Due Date:
- Mentioning the correct date in the invoice helps in getting prompt payments. As payments are the bloodstream of the business, they should be obtained properly. So, mentioning the invoice due date on the invoice makes the clients get updated about the date they must make the payment.
- As the invoice due date assists in receiving quick payments, a smooth cash flow will be experienced by the business. This positive cash flow safeguards the business from a lack of funds. Also, it sets a clear view for the clients about making the payment.
Best Ways to Define Due Dates on Invoices:
Some of the best ways to mention due dates on the invoices are as follows.
1. Date Format: The invoice due date should follow a standard format of DD/MM/YYYY. This clear format gives the client a clear view of the due date.
2. Create Online Invoices: When you use online invoices generated through online invoicing software for small business, easy customization can be carried out and professionalism can be maintained. The manual invoicing process lacks these customization features.
3. Validate the Payment Terms: Reviewing the payment terms mentioned in the invoice results in avoiding payment and invoice disputes.
Overall, the invoice due date plays a major role in the payment collection and smooth business operations. So, mention it accurately in the invoice and get prompt payments.
Do you know about the further process that takes place after the client receives the product or the service? It’s issuing the invoices. While issuing the invoices, clients will experience a sense of s...
If you’re diving into embedded systems or industrial electronics, understanding the right microcontroller is crucial. The Microchip Technology PIC18F25K80-I/MM is a powerful 8-bit MCU designed to balance performance, low power consumption, and versatility. In this comprehensive article, we'll delve into the intricacies of the PIC18F25K80-I/MM, uncovering its definition, key features, specifications, applications, and a closer look at its manufacturer.
PIC18F25K80-I/MM's Overview
The PIC18F25K80-I/MM is an 8-bit microcontroller built on the RISC (Reduced Instruction Set Computing) architecture. Designed by Microchip Technology, it offers a robust set of features tailored for industrial-grade applications requiring reliability and efficient processing. With a 32KB Flash program memory and a maximum CPU frequency of 64 MHz, it strikes a perfect balance between power and efficiency.
Key Features
Let's delve into the standout features that make the PIC18F25K80-I/MM a standout in the world of electronics:
· It operates on a nanoWatt XLP process technology for ultra-low power consumption.
· It supports multiple operating voltages: 2.5V, 3.3V, and 5V.
· It includes 24 general-purpose I/O pins for flexible interfacing.
· It integrates a powerful CAN controller, ideal for automotive and industrial networking.
· It features 5 timers and 4 PWM channels for precise timing and control.
· It has a 12-bit ADC with 8 channels, providing high-resolution analog inputs.
· It offers 2 USART interfaces and supports SPI and I2C communication protocols.
· It has built-in watchdog timer and analog comparators for enhanced system safety.
· The device supports a maximum expanded memory size of 2MB.
· It operates reliably within a temperature range from -40°C to 85°C, meeting industrial standards.
· Packaged in a compact 28-pin QFN surface-mount format for efficient PCB design.
Get more details: PIC18F25K80-I/MM: Features, Specs & More
If you’re diving into embedded systems or industrial electronics, understanding the right microcontroller is crucial. The Microchip Technology PIC18F25K80-I/MM is a powerful 8-bit MCU designed to bala...

In the fast-evolving world of embedded systems and digital design, compact yet powerful FPGAs are essential for developers seeking high performance within tight design constraints. One such solution is the Lattice Semiconductor LCMXO256C-3TN100I—a small-footprint, low-power, high-reliability FPGA from the popular MachXO family. In this comprehensive article, we'll delve into the intricacies of the LCMXO256C-3TN100I, uncovering its definition, key features, specifications, applications, and a closer look at its manufacturer.
LCMXO256C-3TN100I's Overview
The LCMXO256C-3TN100I is a Field-Programmable Gate Array (FPGA) developed by Lattice Semiconductor, designed using a 130nm CMOS process. It belongs to the MachXO family, which is known for offering non-volatile, low-cost, and instant-on programmable logic devices. This model features 256 logic elements and supports various I/O standards with versatile voltage options. It's particularly tailored for industrial-grade applications, operating effectively in temperatures ranging from -40°C to 100°C.
Key Features
Let's delve into the standout features that make the LCMXO256C-3TN100I a standout in the world of electronics:
· Based on 130nm process technology for optimized performance and low power.
· Supports 1.8V, 2.5V, and 3.3V operating supply voltages.
· Includes 256 logic elements, suitable for small-to-medium logic designs.
· Offers 78 user-configurable I/O pins to interface with other hardware.
· Equipped with 2 I/O banks and a wide range of I/O voltage support (1.2V to 3.3V).
· Features in-system programmability (ISP) and reprogrammability for design flexibility.
· Integrates 8 global clocks for better timing and synchronization.
· Built with 2048 bits of distributed RAM for efficient data handling.
· Low maximum propagation delay time of 4.9ns.
· Comes in a 100-pin TQFP package with a compact 14x14mm footprint.
Get more details: LCMXO256C-3TN100I: Features, Specs & More
In the fast-evolving world of embedded systems and digital design, compact yet powerful FPGAs are essential for developers seeking high performance within tight design constraints. One such solution i...

https://www.times-standard.com/2025/05/07/soccer-players-celebrate-50ish-years-of-sport-in-humboldt-county/
#times-standard

https://www.times-standard.com/2025/03/10/trump-administrations-eo-may-result-in-roll-back-of-historic-preservation-efforts/
#times-standard
- HippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models
original article — hacker news - Did UCLA Just Cure Baldness?
original article — hacker news - Transformer – Spreadsheet
original article — hacker news - Easy 6502
original article — hacker news - There May Not Be Aha Moment in R1-Zero-Like Training
original article — hacker news - Understanding Reasoning LLMs
original article — hacker news - It is time to standardize principles and practices for software memory safety
original article — hacker news - Robust autonomy emerges from self-play
original article — hacker news - Maria Montessori
original article — hacker news - Show HN: SQLite disk page explorer
original article — hacker news
- HippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models
original article — hacker news - Did UCLA Just Cure Baldness?
original article — hacker news - Transformer – Spreadsheet
ori...